
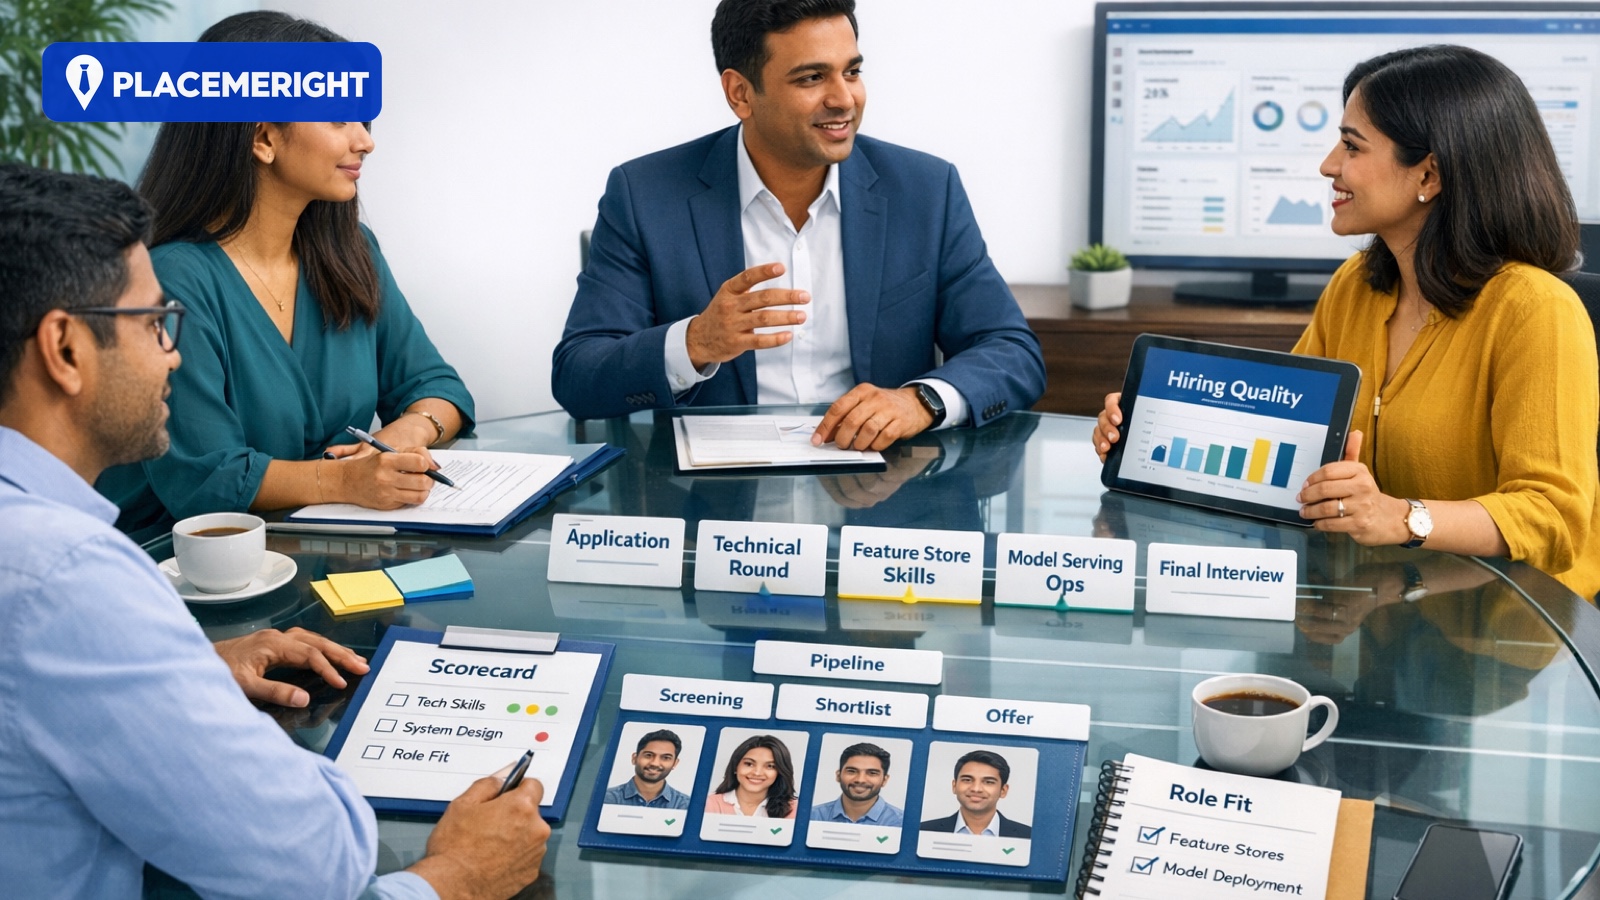
Why this role is hard to hire well (and why it matters now)
Hiring ML Platform Engineers is rarely about checking tools on a resume. The real signal is whether a candidate can make trade-offs under pressure and still deliver predictable outcomes—especially around platform engineering, ML delivery. This section helps you separate confident storytelling from production-grade judgment so you can shortlist faster and reduce bad hires.
If you want help improving shortlist quality and interview speed, explore RPO services and learn more about PlaceMeRight on About. For end-to-end hiring support, see Tech recruitment and our IT recruitment agency in India.
What you’re really hiring for
You’re hiring outcomes, not tasks. Strong candidates can:
- explain what they owned (not “team did”)
- make trade-offs with evidence
- communicate risk early and reduce rework
Shortlisting signals (what good looks like)
Must-have signals
- Can define success metrics and model serving ops without ambiguity.
- Has a clear approach to feature pipelines (owners, SLAs, monitoring).
- Can explain cost/performance trade-offs and monitoring discipline impacts.
- Communicates definitions and changes clearly to stakeholders.
Strong signals
- Builds governance that scales (access controls, lineage, change mgmt).
- Can debug data incidents with a hypothesis-first process.
- Knows how to prevent dashboard/metric chaos with standards.
- Can run a roadmap with capacity planning and trade-offs.
Red flags
- Cannot explain which decisions the work improves.
- Ignores data quality and calls it “someone else’s job”.
- No cost awareness; only “bigger warehouse / more compute”.
- Weak stakeholder alignment; definitions drift over time.
A practical interview loop (India-ready)
Use a structured loop that is fast to run and hard to game:
Round 1: Screen (40 minutes)
- Ask for a metric or dataset they owned and how model serving ops was improved.
- Probe for feature pipelines: owners, SLAs, monitoring, and change management.
- Assess stakeholder alignment: definitions + governance rules.
Round 2: Case study (60 minutes)
- Design a metrics layer for a workflow; include monitoring discipline trade-offs (cost vs freshness).
- Ask for model choices, ownership, SLAs, and rollout plan.
- Score clarity, practicality, and ability to prevent metric chaos.
Round 3: Debugging scenario (45 minutes)
- Scenario: dashboard numbers drift after a release.
- Ask for triage order, rollback/patch decision, and prevention steps.
Work sample (30–60 minutes) that predicts real work
Keep the task short, job-real, and scorable:
- Draft a metrics spec: definitions, owners, SLAs, and change management (focus: model serving ops).
- Given a broken dashboard, list 10 triage checks in order (focus: feature pipelines).
- Propose a monitoring plan for monitoring discipline with alerts and ownership.
Scorecard (copy/paste)
Rate each bucket: Strong / Acceptable / Risk.
1. Modeling judgment (definitions, trust, usability) 2. Data quality discipline (SLAs, monitoring, ownership) 3. Cost/performance thinking (trade-offs, optimization) 4. Stakeholder alignment (definitions, adoption, conflicts) 5. Operational ownership (debugging, change management)
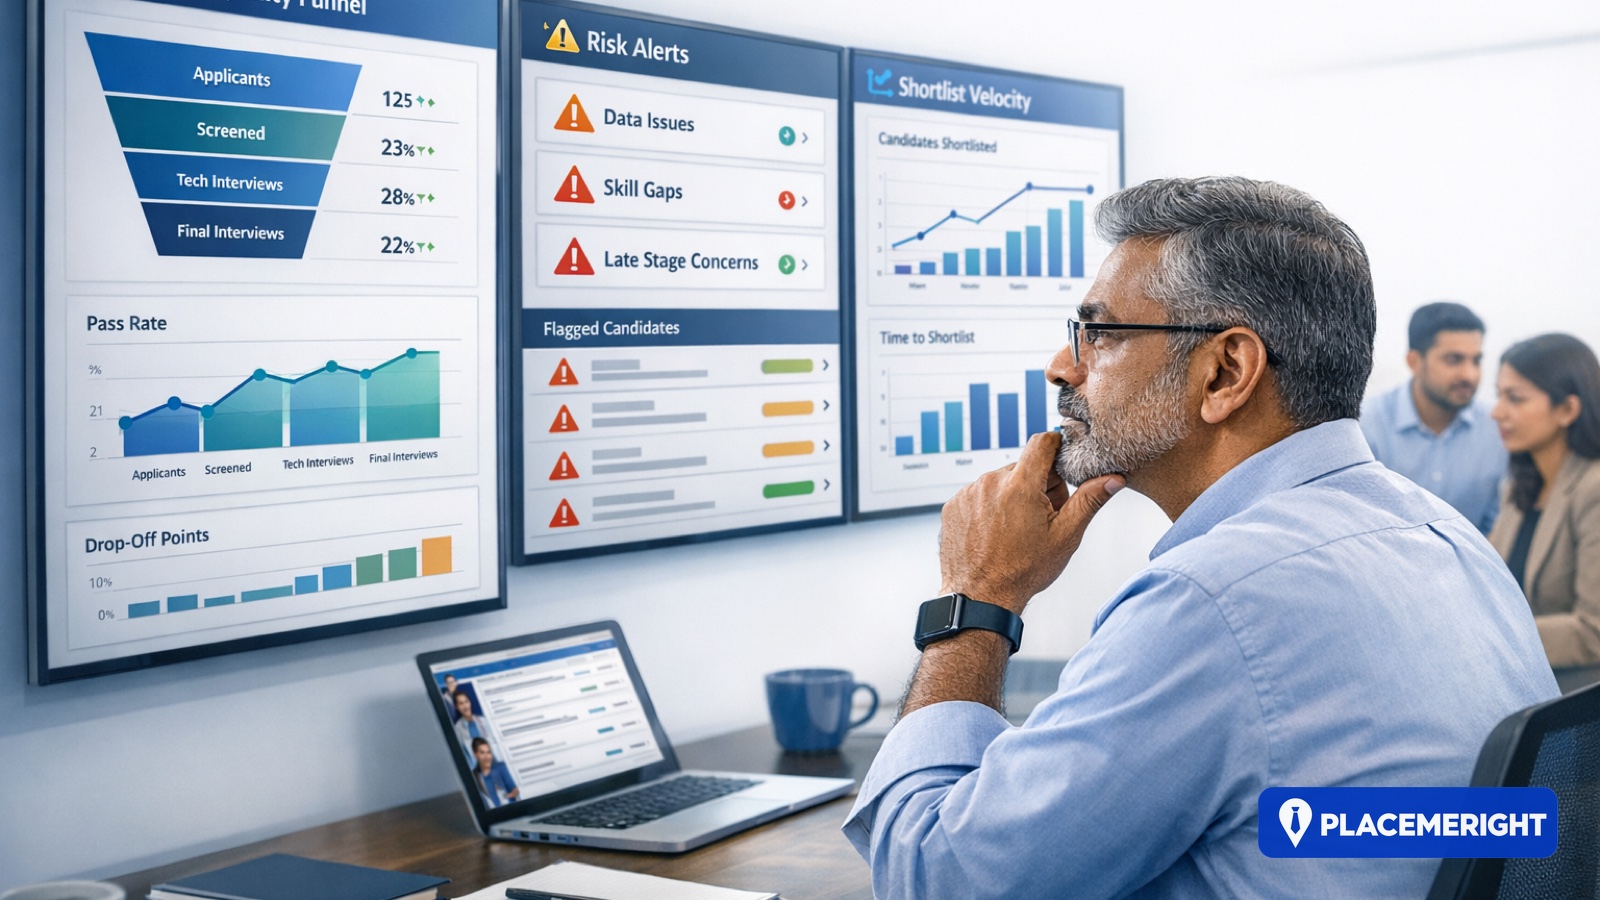
Common mistakes that slow hiring (and how to avoid them)
1. Overweighting buzzwords and underweighting ownership stories. 2. No consistent rubric—interviewers improvise and outcomes become random. 3. Skipping job-real scenarios—false positives slip through. 4. Not communicating timelines and next steps—candidates drop out.
Quick checklist (copy/paste)
- Confirm the role charter (outcomes, scope, stakeholders).
- Define 5–7 signals to test (must-haves vs trainable).
- Run a consistent loop (same questions, same scoring).
- Use a scorecard with clear pass/fail thresholds.
- Keep the process fast (time-box rounds; avoid extra rounds).
- Track funnel metrics (time-to-interview, pass-through, offer acceptance).
Interview question bank (copy/paste)
Use these prompts to quickly test real-world signals (not trivia):
- Define a metric that measures model serving ops. What’s the exact definition and owner?
- How do you set SLAs for feature pipelines without creating reporting theater?
- When numbers don’t match, what are your first 10 checks (in order)?
- How do you balance freshness vs cost while optimizing monitoring discipline?
- How do you prevent metric drift when teams ship quickly?
- Describe a time stakeholders disagreed on definitions. How did you resolve it?
- What dashboards do you want in your first 30 days to understand risk and adoption?
- What’s a common data anti-pattern you would remove immediately and why?
Related reading
If you’re improving hiring outcomes, these related guides can help:
- Hiring Prompt Engineers in India: Interview Loop for Evaluation, Guardrails, and Business Fit
- Hiring LLM Ops Engineers in India: Screening for Cost Discipline, Safety, and Reliability
- Hiring AI Governance Leads in India: Interview Signals for Policy, Risk, and Measurement
- Hiring Design Ops Managers in India: Interview Loop for Process, Quality, and Cross-Team Alignment
- Hiring UX Writers in India: Screening for Clarity, IA, and Product Collaboration
- Hiring Content Designers in India: Interview Signals for UX Copy Systems and Consistency
FAQs
How do we test business impact without subjectivity?
Ask for one decision their work changed, then validate how definitions, instrumentation, and ownership were handled. For ML Platform Engineers roles, ask for one concrete example (a shipped project, an incident/post-mortem, or a measurable improvement) and then probe constraints, trade-offs, and validation steps. This forces specificity and reduces false positives.
What’s the fastest way to improve data trust after hiring?
Define metric owners + SLAs, add monitoring for critical pipelines, and run a weekly data quality review with escalation paths. For ML Platform Engineers roles, ask for one concrete example (a shipped project, an incident/post-mortem, or a measurable improvement) and then probe constraints, trade-offs, and validation steps. This forces specificity and reduces false positives.
Conclusion
Better hiring outcomes come from clarity: define what “good” means, test it directly with scenarios, and score consistently. You’ll reduce false positives and speed up offers—without lowering the bar.
CTA (PlaceMeRight)
If you’re hiring in India and want faster shortlists with structured screening and clear interview operations, PlaceMeRight can help.
- Talk to us: Contact
- Explore tech hiring: Tech recruitment and IT recruitment agency in India
- For embedded hiring pods: RPO services
References
- https://developers.google.com/search/docs/fundamentals/creating-helpful-content
- https://owasp.org/www-project-top-ten/
- https://sre.google/sre-book/table-of-contents/
- https://itrevolution.com/product/accelerate/
Related PlaceMeRight resources
Our Tech Recruitment Services by City
Looking to hire vetted software engineers or scale your engineering teams in India's leading tech hubs? Explore our localized recruitment services:
Tags: